
What changed
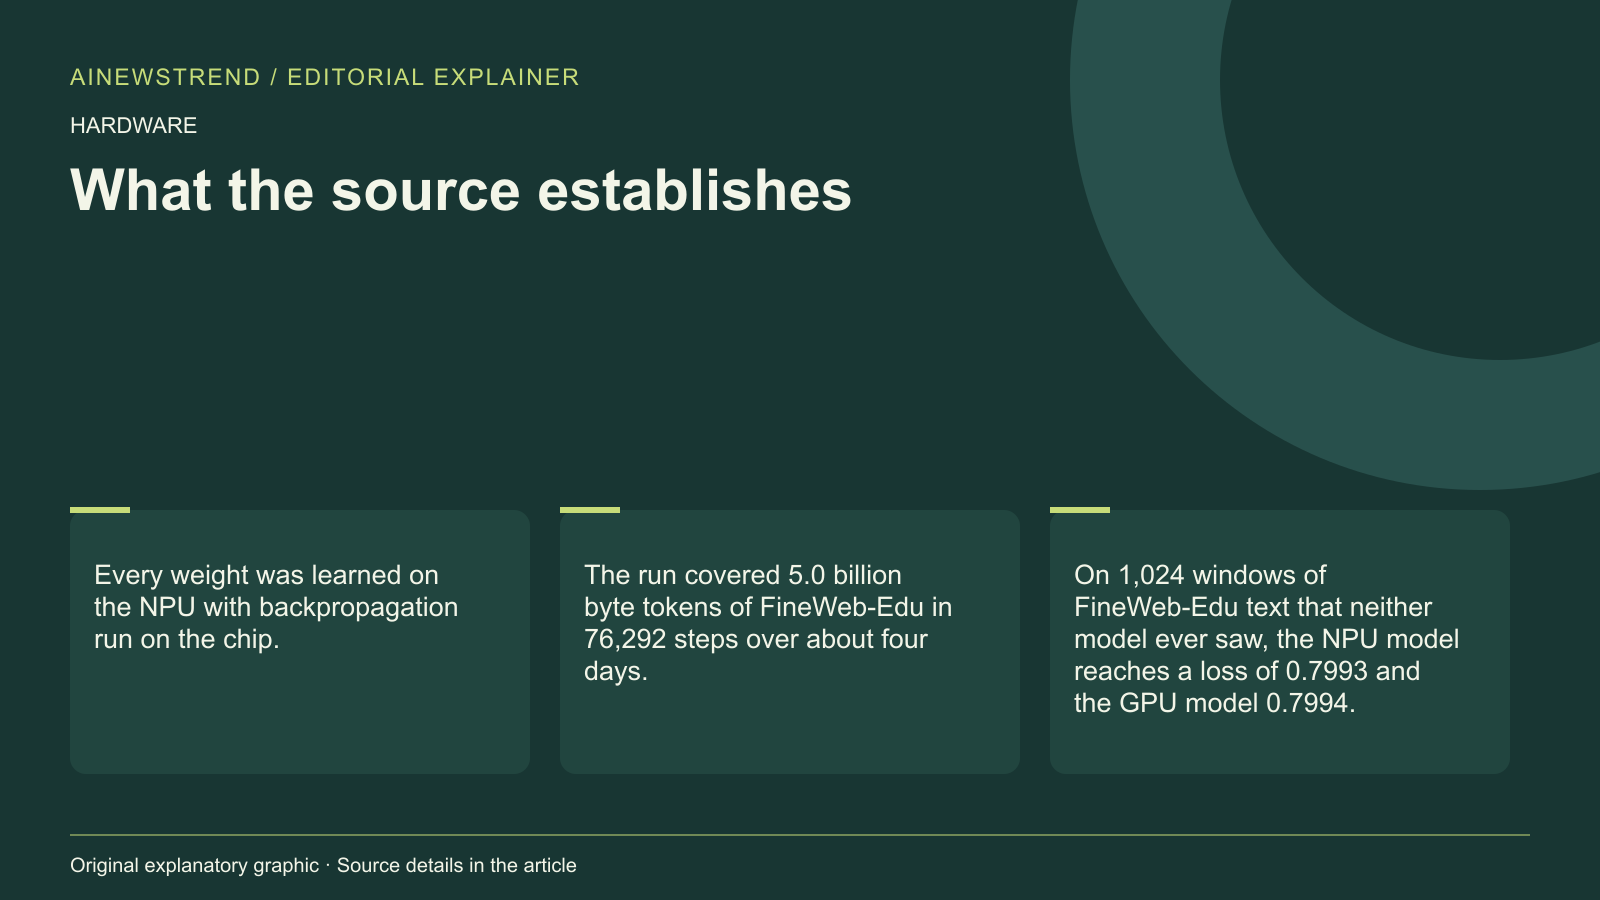
Hugging Face announced the pretraining of VKORE-325M-NPU-Base, a 325.6M parameter decoder-only language model, from random initialization on a commercial inference-only NPU. Every weight was learned on the NPU with backpropagation run on the chip. No pretrained weights were used. The run covered 5.0 billion byte tokens of FineWeb-Edu in 76,292 steps over about four days. In parallel, the same model was trained on a B200 GPU with the same initialization, data, batch, and learning-rate schedule.
What this means in practice
The NPU model reached a loss of 0.7993 on 1,024 windows of FineWeb-Edu text that neither model ever saw, while the GPU model reached 0.7994. The paired difference is -0.0001 with a standard error of 0.0007, and the NPU model is lower on 50.1% of windows. Both sets of weights and the evaluation script are public, allowing anyone to check the result in a few minutes. The model uses a byte-level vocabulary, with no tokenizer to tune, and the reported loss is cross entropy per byte, which converts directly to bits per byte.
Limitations and availability
The NPU model is trained on an inference-only NPU, which is not designed for training tasks. The training process required special engineering to make long runs stable on an inference-only stack. The model and evaluation script are available on the Hugging Face Hub at FINAL-Bench/VKORE-325M-NPU-Base. The supplied announcement does not specify the exact hardware used for the NPU training or the specific NPU model.