
What changed
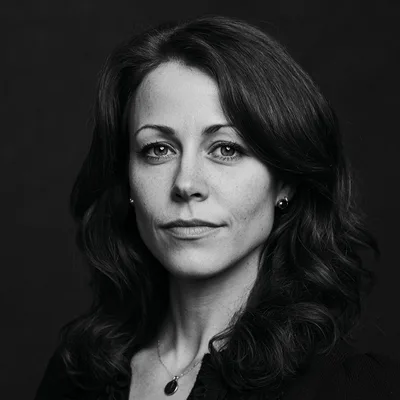
AI agents are changing how enterprises create, move and govern information, with data observability becoming a prerequisite rather than a nice-to-have. KubeCon organizers added a dedicated AI inference and agentic track this year, reflecting the industry's rapid evolution from chatbots to retrieval, fine-tuning and agents. Sanjeev Mohan, principal at SanjMo, a data and AI advisory firm, emphasized that AI success depends on a solid foundation, including observability and transparency.
What this means in practice
Mohan explained that traditional data pipelines, which worked for batch reports, are no longer sufficient for AI agents. These agents access databases directly and spin up short-lived databases to test different chains of thought before taking action. For example, an agent reviewing a loan application might query census records and social media before making a decision, raising questions about how such decisions get audited.
Governance is now critical, and this is not like past governance models where data was governed and then used for deterministic reports. Instead, data observability must be part of the architecture itself, not an afterthought.
Mohan’s book, published in June 2026, explores how AI agents as first-class data consumers are redefining architectural principles. Future platforms will need to blend structured and unstructured data in a single converged system, with context built in runtime.
Limitations and availability
The supplied announcement does not specify exact technical limitations or availability timelines for the new data observability requirements. However, Mohan notes that the context for the same task can vary significantly between users, leading to new kinds of databases. The shift toward runtime context and converged data systems is expected to shape future platforms, though specific implementation details remain to be determined.