
What changed
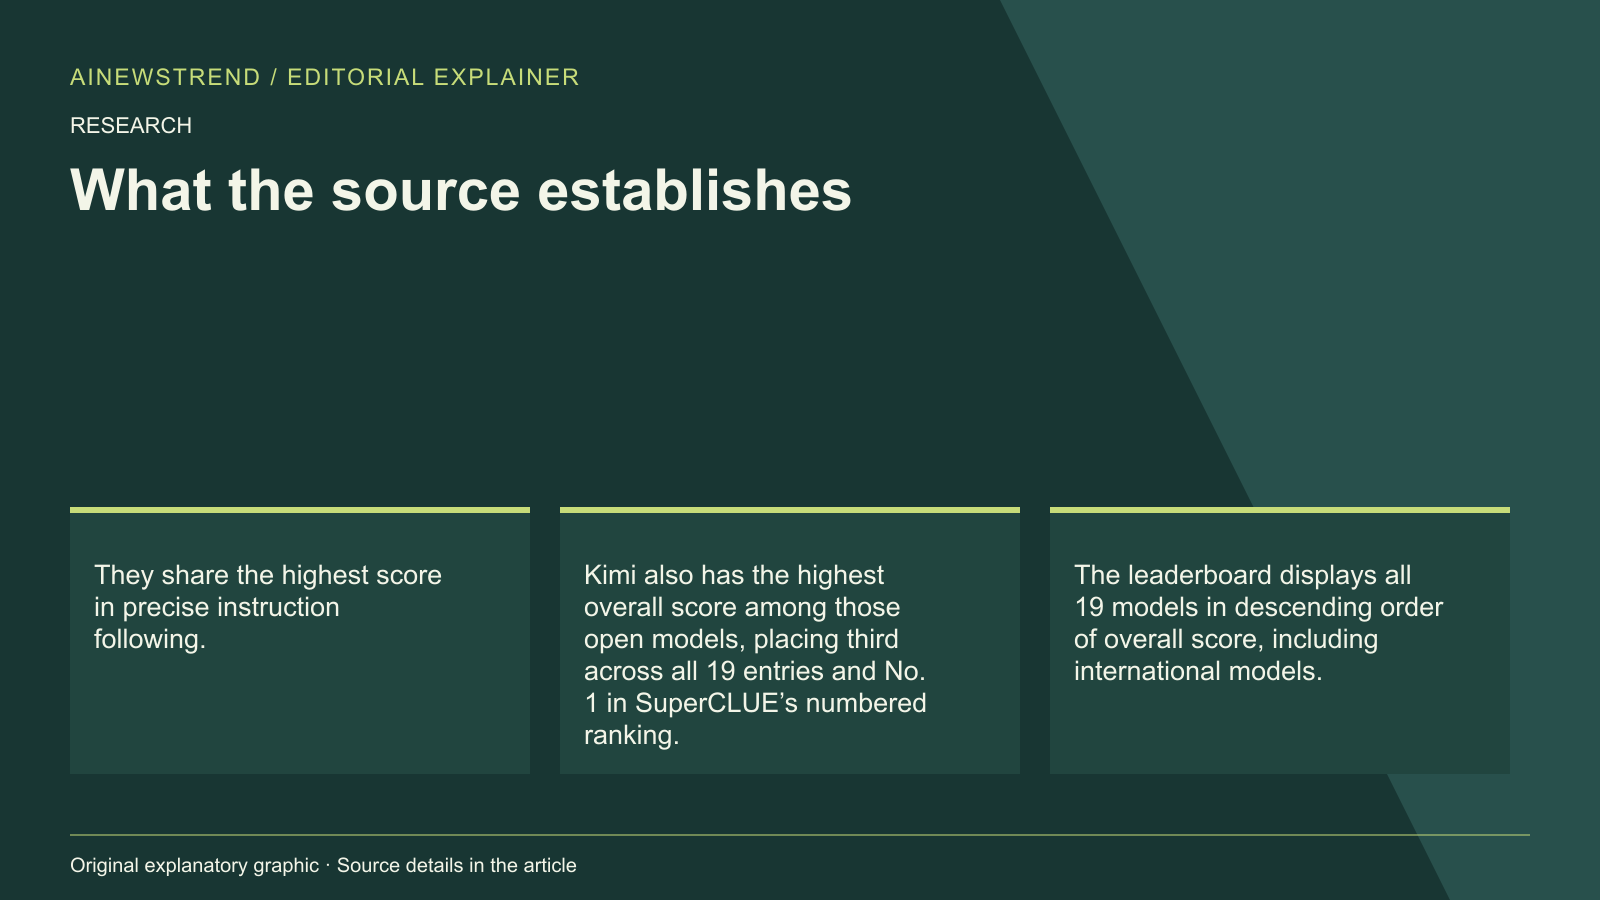
On November 5, 2026, the SuperCLUE benchmark results were released, showcasing the performance of 19 models across five categories. The results emphasize that model selection benefits from a category-level perspective, with different models excelling in specific tasks.
GPT-6.1-Sol leads in agentic coding and mathematical and scientific reasoning, while Gemini-4-Argon excels in hallucination control and ultra-long context. Kimi-K3.1-Pro is the top-performing open model overall, placing third in the full ranking.
What this means in practice
For developers and researchers, the SuperCLUE results provide a clear view of which models are best suited for specific tasks. For example, DeepSeek-V4.1-Flash-1017 leads in coding among open models, while Darwin-180B-RSI-R3 is the top open model in mathematical and scientific reasoning.
Kimi-K3.1-Pro is the top open model in hallucination control and ultra-long context. The results also highlight that a model's overall ranking may not reflect its performance in a specific task, underscoring the importance of category-level analysis.
Limitations and availability
The SuperCLUE benchmark includes 19 models, with 12 labeled as open and seven as closed. The open/closed labels are based on SuperCLUE’s classification and do not represent an independent assessment of license terms or commercial use eligibility.
Developers should consult each model’s repository, model card, and license for deployment details. International models outside China are excluded from the numbered ranking due to SuperCLUE’s policy, not performance.
The results are based on benchmark points, and scores should not be interpreted as hallucination rates or error rates without additional context.