
What changed
Salesforce announced the release of SOV-Transcribe-1, an open-weight speech model with 4 billion active parameters (26 billion total), built for non-streaming automatic speech recognition (ASR). The model is designed to handle real-world speech scenarios, including support for multiple languages, entity understanding, and robustness to accents and noise.
What this means in practice
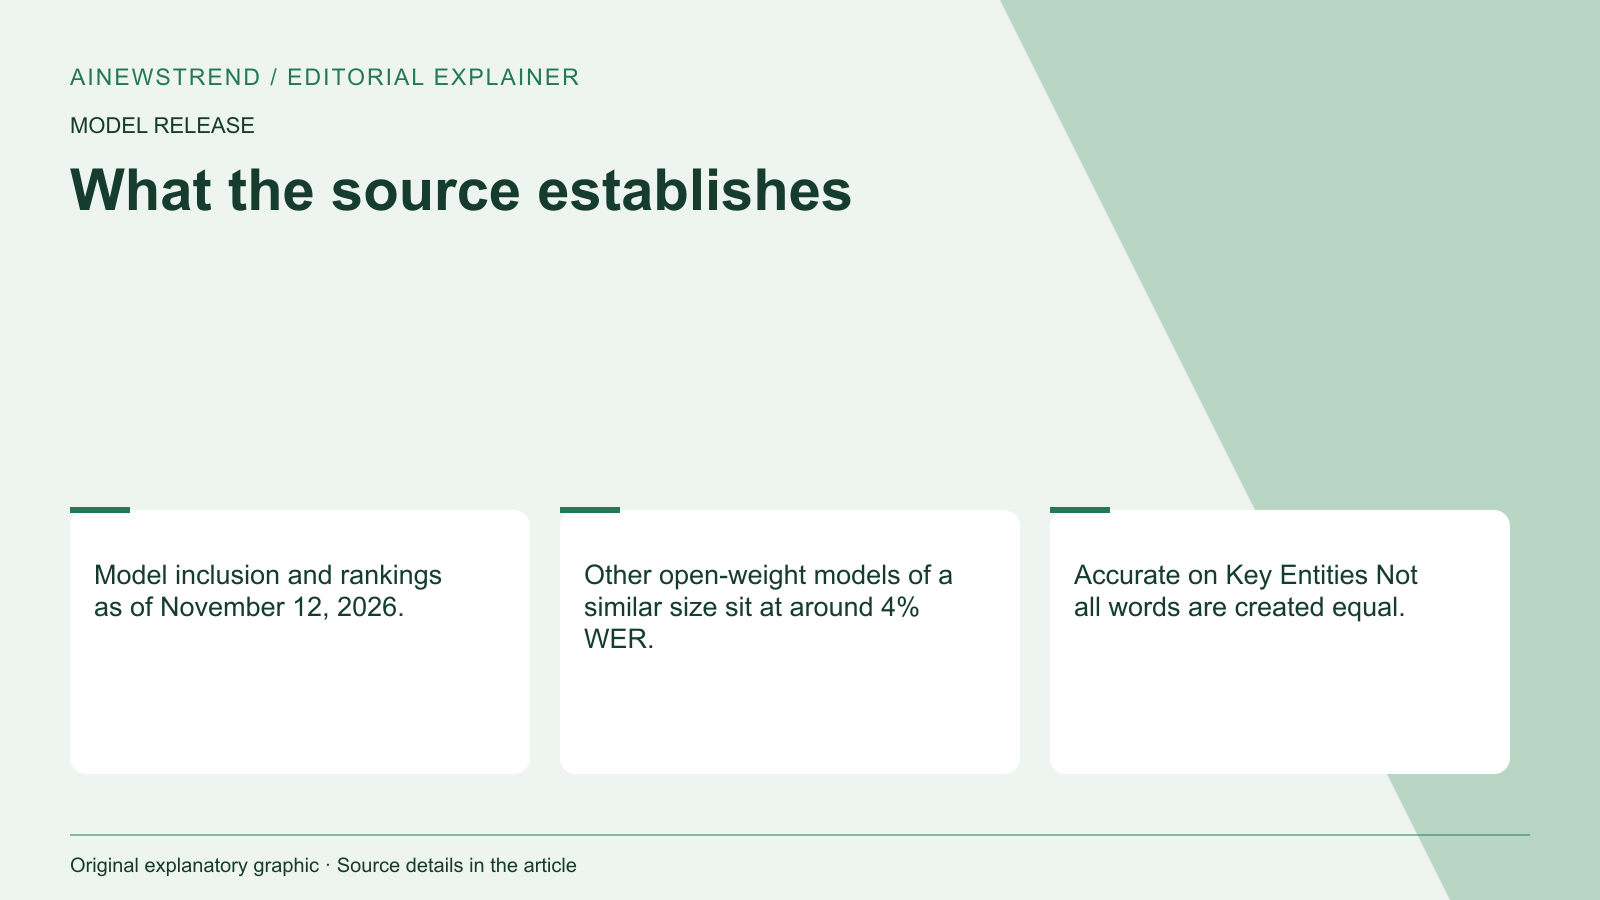
SOV-Transcribe-1 offers best-in-class English transcription and strong entity understanding, such as phone numbers and emails. It is available under the Apache 2.0 license and can be used by developers and enterprises to build voice agents, dictation tools, and call transcription systems while retaining control over critical data. The model ranks #1 among open-weight models for non-streaming speech-to-text on Artificial Analysis and #2 of 23 systems on VoiceCodeBench.
Limitations and availability
The model is available on Hugging Face under the Apache 2.0 license. It has a word error rate (WER) of 2.28% for non-streaming speech-to-text, outperforming several other models. SOV-Transcribe-1 is also robust across accents, achieving an 8.21% average WER on AppTek Call-Center Dialogues. The model's performance in real-world environments, such as HALAS, is 25.69% WER, lower than other open-weight models. The model supports style steering and context biasing for difficult domains, improving accuracy for critical entities.