
What changed
AMD has detailed the GLM-5.3-Flash model, a sparse mixture-of-experts (MoE) model with a hybrid attention stack, designed for long-context serving on the MI300X server. The model runs on a single eight-GPU node and uses FP8 checkpoint weights, with a total of 320 billion parameters and about 18 billion active parameters per token. It supports a maximum context length of 1,048,576 tokens, though the blog serves requests up to 131,072 tokens. The model uses two parallelism strategies—TP8 (tensor parallelism) and DP8+EP8 (data and expert parallelism)—to manage the KV cache and optimize throughput for different request shapes.
What this means in practice
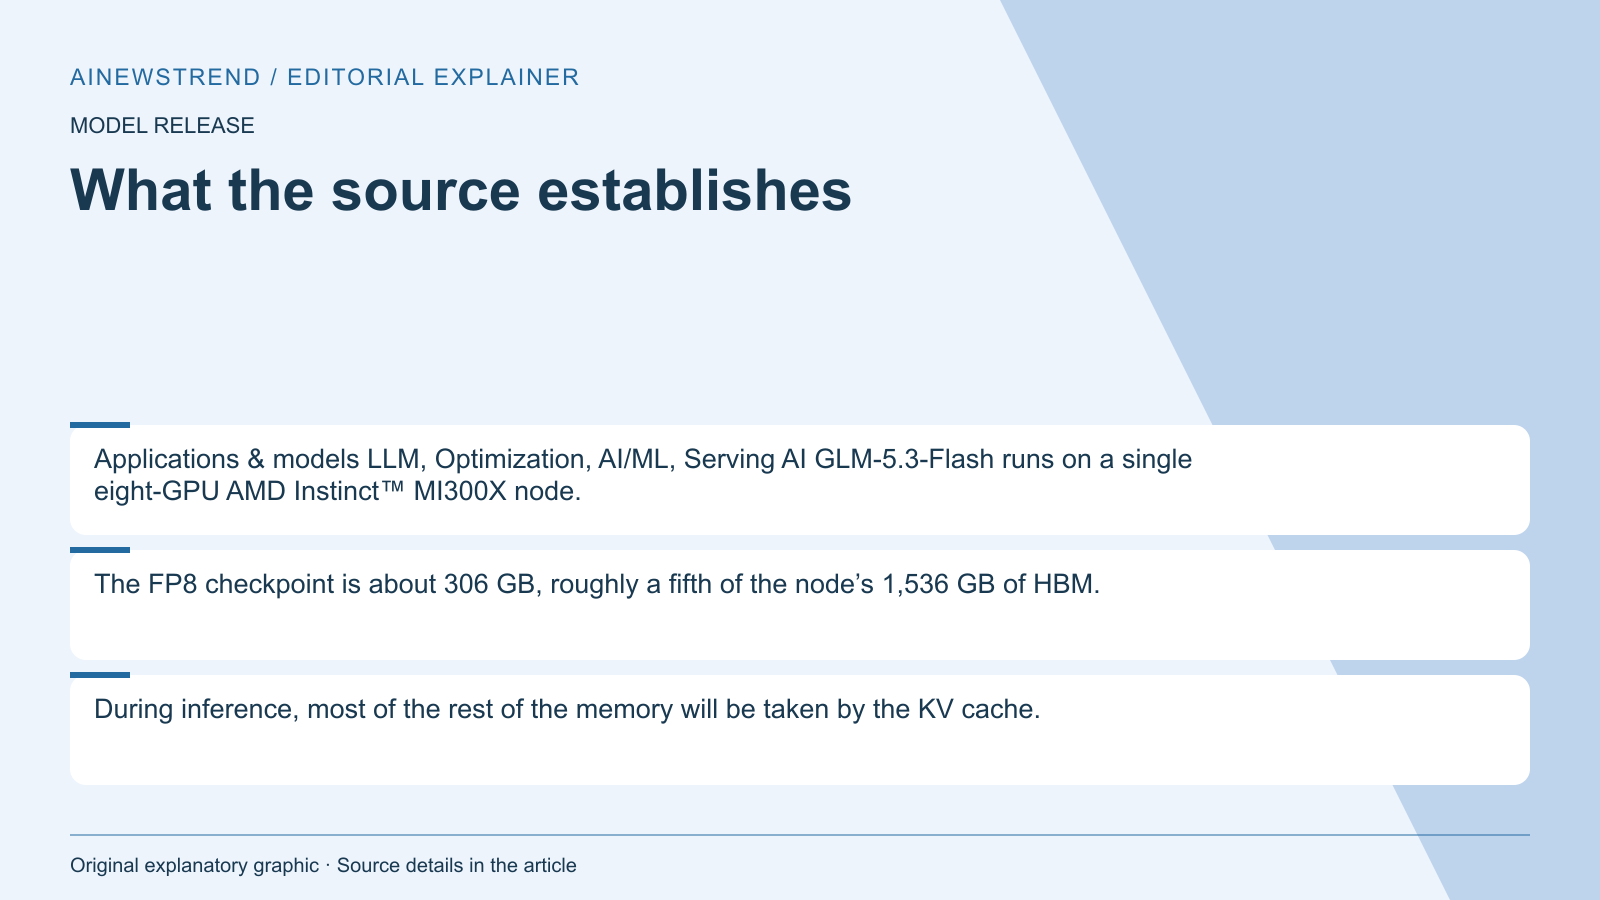
The GLM-5.3-Flash model is optimized for long-context, high-concurrency serving scenarios. The FP8 checkpoint is approximately 306 GB, which is about a fifth of the node’s 1,536 GB of HBM. The KV cache, which stores attention keys and values for each token, consumes most of the remaining memory. The model’s performance depends on the parallelism strategy and the KV cache precision. TP8 offers lower latency for single requests but has a smaller cache capacity, while DP8+EP8 allows for more concurrent sessions by distributing the cache across GPUs. The choice of KV cache precision (BF16 or FP8) affects the number of tokens that can be stored, with FP8 allowing nearly twice as many tokens.
Limitations and availability
The model’s performance is constrained by the KV cache, which becomes the scarce resource when handling many long sessions. The blog outlines the trade-offs between TP8 and DP8+EP8, showing that DP8+EP8 can support up to 441 concurrent 96k/32k sequences with BF16 cache, compared to 76 with TP8. The model is available on the MI300X server node, which consists of eight MI300X GPUs with 192 GB of HBM each. The blog provides detailed measurements and comparisons for different request shapes, but the exact availability and deployment steps are not specified in the snapshot.