
What changed
AWS has introduced workload recovery and expanded infrastructure checks on Amazon SageMaker HyperPod. These features aim to address issues where training jobs fail due to subtle hardware faults or stalled processes, which can lead to wasted compute resources and reduced goodput.
What this means in practice
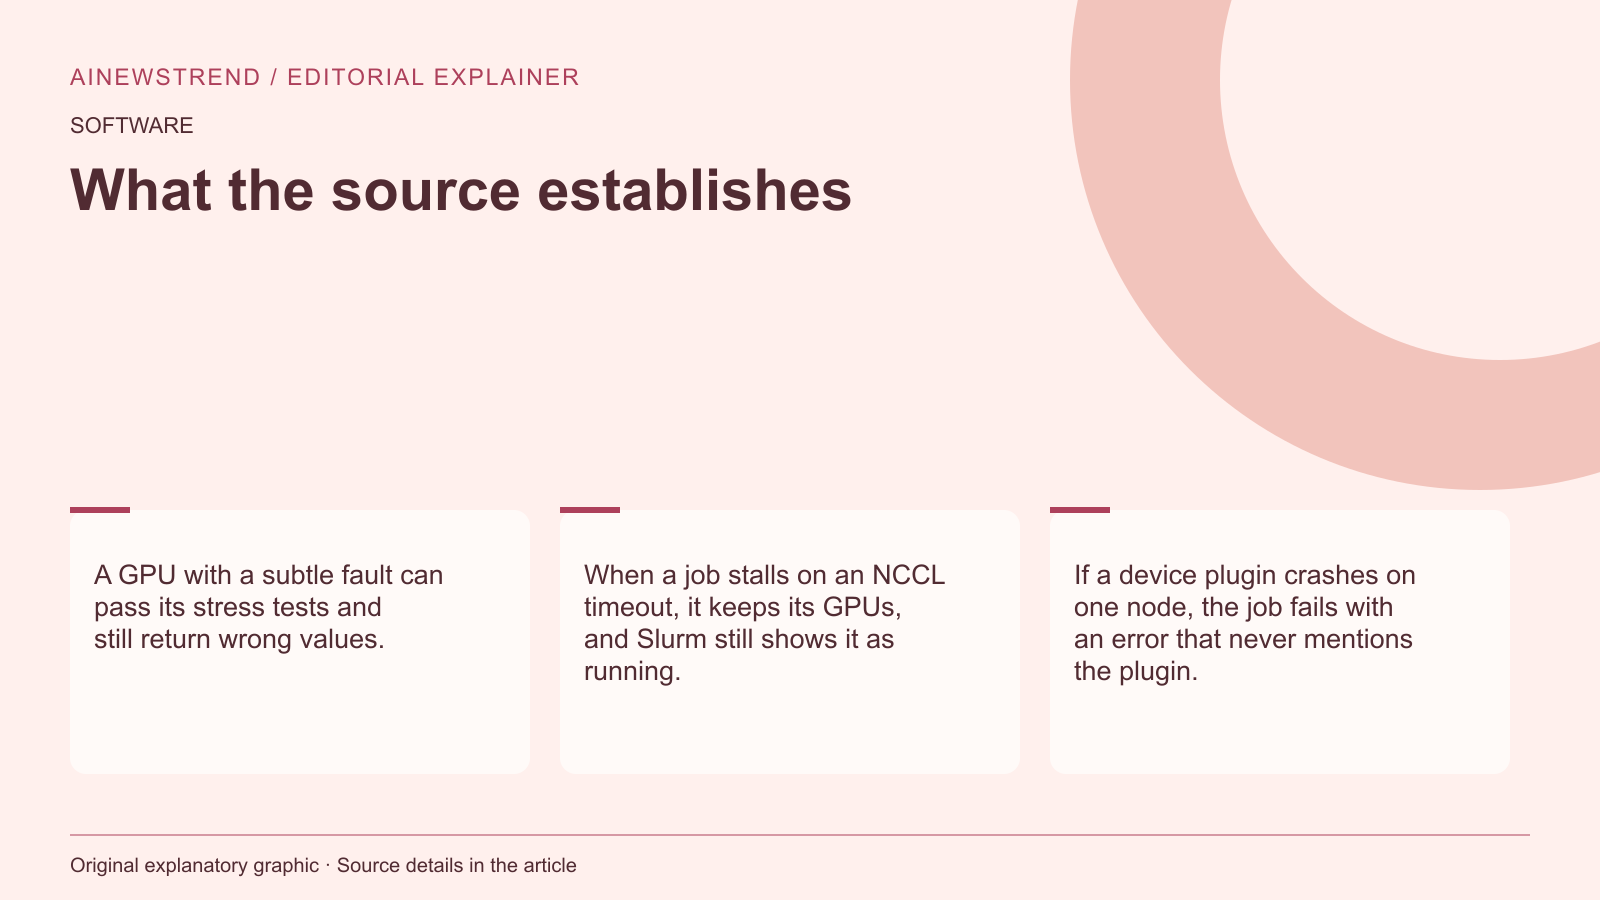
The new capabilities include MultiNodeTrainingValidation, a deep health check that trains a small model on instances and across instances of the same type to detect numerical faults. If the loss becomes NaN or infinite, or training doesn’t finish in time, the instance is flagged. The HyperPod Kubernetes Resource Monitoring Agent continuously watches the Kubernetes layer of an EKS cluster for issues like crash-looping device plugins or missing DaemonSets, reporting these as events and logs. Hung job detection identifies jobs that have stopped making progress, writing events to CloudWatch and optionally canceling the job to requeue it via Slurm.
Limitations and availability
The existing HyperPod resiliency features check individual nodes for hardware faults but do not ensure GPUs compute correctly or that Kubernetes components are healthy. MultiNodeTrainingValidation is available on EKS clusters with supported EFA-enabled NVIDIA GPU instances. Hung job detection is new for Slurm clusters, while EKS clusters already have some detection capabilities. The features are designed to improve scheduling, runtime, and program goodput by catching failures earlier and reducing wasted compute resources.