
What changed
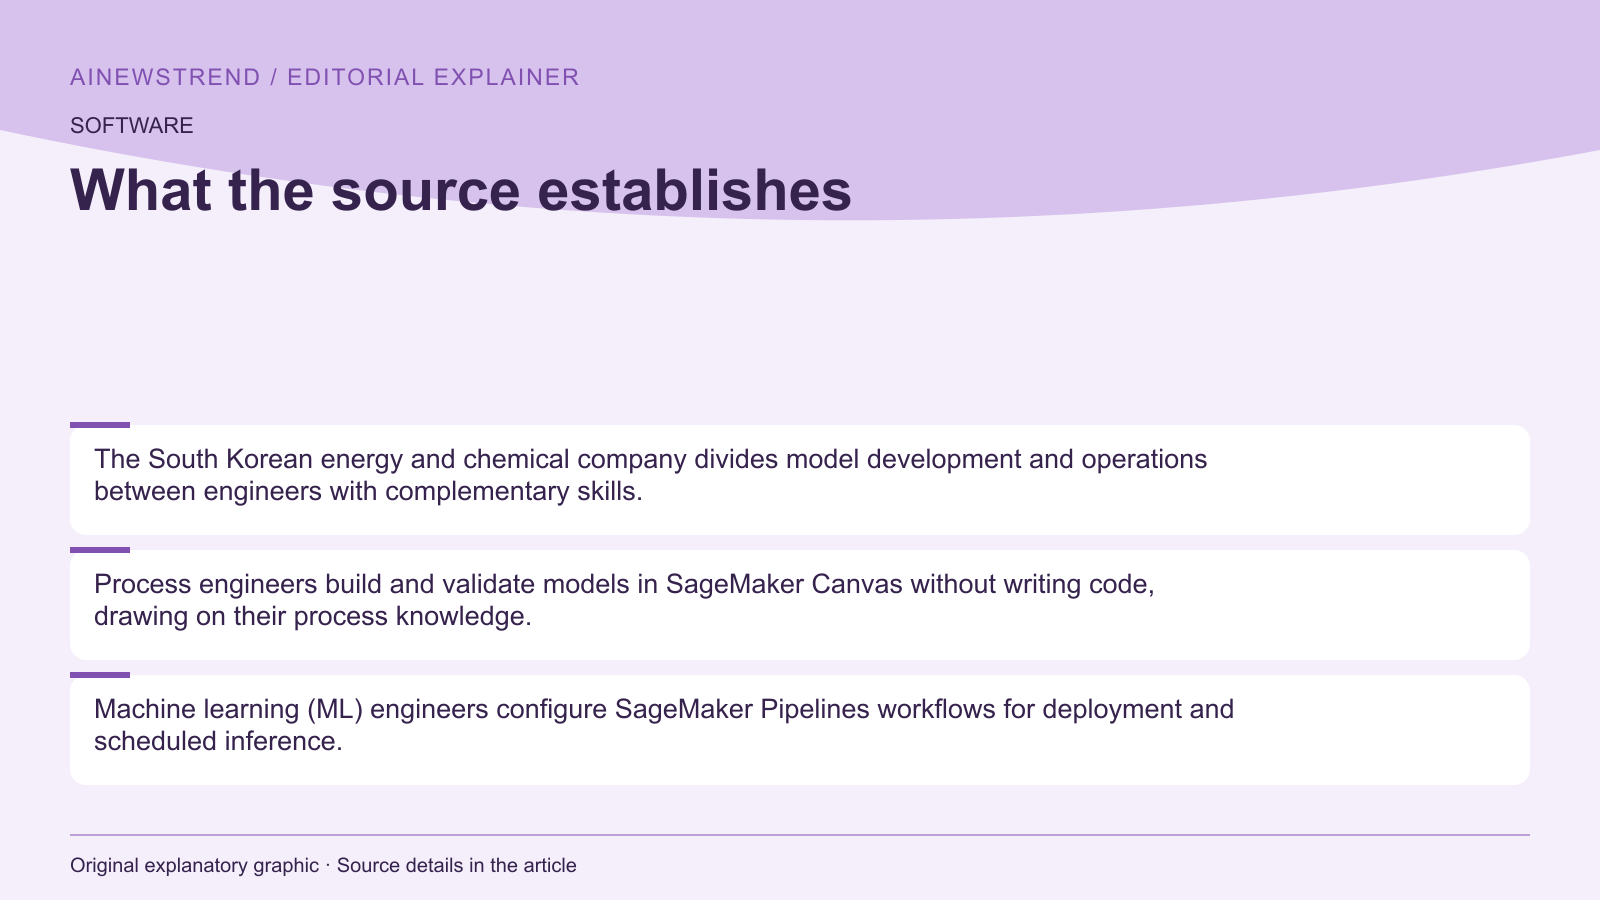
GS Caltex, a South Korean energy and chemical company, has integrated Amazon SageMaker Canvas with Amazon SageMaker Pipelines to automate model deployment. Process engineers use SageMaker Canvas to build and validate models without coding, while ML engineers configure Pipelines for deployment and scheduled inference. This integration automates the handoff of models and preprocessing flows from Canvas to Pipelines, reducing deployment time from about a week to a few hours.
What this means in practice
The integration allows GS Caltex to run batch inference every 30 minutes, reducing the need for continuously running endpoints and lowering inference costs. ML engineers now manage model versions and execution history, while process engineers validate model predictions based on their domain knowledge. The workflow reuses validated preprocessing flows and models from SageMaker Canvas, ensuring consistency between development and production environments.
Limitations and availability
The solution requires a model built and evaluated in SageMaker Canvas, along with CSV data for inference and an S3 bucket. A SageMaker execution role and an Amazon EventBridge role with permissions are also needed. The reference implementation is available in a GitHub repository, with code examples focusing on component connections. The full implementation uses a sample loan classification model, so users must adjust configurations to match their model’s input and output formats. The solution is available for AWS customers using SageMaker Canvas and Pipelines.